
Transaction Specification
Transaction Overview
Lance implements Multi-Version Concurrency Control (MVCC) to provide ACID transaction guarantees for concurrent readers and writers. Each commit creates a new immutable table version through atomic storage operations. All table versions form a serializable history, enabling features such as time travel and schema evolution.
Transactions are the fundamental unit of change in Lance. A transaction describes a set of modifications to be applied atomically to create a new table version. The transaction model supports concurrent writes through optimistic concurrency control with automatic conflict resolution.
Commit Protocol
Storage Primitives
Lance commits rely on atomic write operations provided by the underlying object store:
- rename-if-not-exists: Atomically rename a file only if the target does not exist
- put-if-not-exists: Atomically write a file only if it does not already exist (also known as PUT-IF-NONE-MATCH or conditional PUT)
These primitives guarantee that exactly one writer succeeds when multiple writers attempt to create the same manifest file concurrently.
Manifest Naming Schemes
Lance supports two manifest naming schemes:
- V1:
{version}.manifest- Monotonically increasing version numbers (e.g.,1.manifest,2.manifest) - V2:
{u64::MAX - version:020}.manifest- Reverse-sorted lexicographic ordering (e.g.,18446744073709551614.manifestfor version 1)
The V2 scheme enables efficient discovery of the latest version through lexicographic object listing.
Transaction Files
Transaction files store the serialized transaction protobuf message for each commit attempt. These files serve two purposes:
- Enable manifest reconstruction during commit retries when concurrent transactions have been committed
- Support conflict detection by describing the operation performed
Inline Transaction Sections
Small transactions may also be embedded in the manifest file. The manifest stores the byte position of the length-prefixed Transaction message in transaction_section (field 23). Readers that do not recognize this manifest field ignore it, so adding a Transaction operation cannot prevent those readers from opening the dataset.
Decoding an inline transaction while opening a manifest is an optional cache optimization. An undecodable or unsupported Transaction message must not make the manifest unreadable. A Transaction whose operation holds a field number in the reserved range 100-199 that the reader does not recognize is an operation from a newer writer. Readers must treat it as an unknown operation that conflicts with every concurrent transaction, and must not re-encode or commit it.
transaction_section_deprecated (field 21) is the legacy inline position. New writers must leave it absent. Readers may use it to retrieve a transaction from an old manifest when field 23 is absent.
Commit Algorithm
The commit process attempts to atomically write a new manifest file using the storage primitives described above. When concurrent writers conflict, the system loads transaction files to detect conflicts and attempts to rebase the transaction if possible. If the atomic commit fails, the process retries with updated transaction state. For detailed conflict detection and resolution mechanisms, see the Conflict Resolution section.
Validation
Before writing a manifest, a writer validates the manifest its transaction
would produce. These checks apply to every transaction, whether it names one of
the operations below or carries a CompositeOperation. A transaction that
fails one is rejected rather than committed, and a retry validates again
against the version it rebased onto.
- Required fields have data. A field is required when it and all of its ancestors are non-nullable. Every fragment the transaction adds, or whose data files it changes, must store data for each required field; a fragment without it would read the field back as nulls. When the transaction makes a field required, by adding it as non-nullable or by making it non-nullable, every fragment is checked.
- Every data file stores at least one field.
- Fragment IDs are unique within the manifest.
- Field IDs follow the allocation rules. When the manifest sets
max_allocated_field_id, every field ID it references must satisfy the non-reusable field ID rules.
Transaction Types
The authoritative specification for transaction types is defined in protos/transaction/.
Each transaction contains a read_version field indicating the table version from which the transaction was built,
a uuid field uniquely identifying the transaction, and an operation field specifying one of the following transaction types:
In the following section, we will describe each transaction type and its compatibility with other transaction types. This compatibility is not always bi-directional. We are describing it from the perspective of the operation being committed. For example, we say that an Append is not compatible with an Overwrite which means that if we are trying to commit an Append, and an Overwrite has already been committed (since we started the Append), then the Append will fail. On the other hand, when describing the Overwrite operation, we say that it does not conflict with Append. This is because, if we are trying to commit an Overwrite, and an Append operation has occurred in the meantime, we still allow the Overwrite to proceed.
Append
Adds new fragments to the table without modifying existing data. Fragment IDs are not assigned at transaction creation time; they are assigned during manifest construction.
Append protobuf message
Append Compatibility
The append operation is one of the most common operations and is designed to be compatible with most other operations, even itself. This is to ensure that multiple writers can append without worry about conflicts. These are the operations that conflict with append:
- Overwrite
- Restore
- UpdateMemWalState
Delete
Marks rows as deleted using deletion vectors.
May update fragments (adding deletion vectors) or delete entire fragments.
The predicate field stores the deletion condition, enabling conflict detection with concurrent transactions.
Delete protobuf message
message Delete {
  /* The fragments to update
   *
   * The fragment IDs will match existing fragments in the dataset.
   */
  repeated DataFragment updated_fragments = 1;
  // The fragments to delete entirely.
  repeated uint64 deleted_fragment_ids = 2;
  /* The predicate that was evaluated
   *
   * This may be used to determine whether the delete would have affected
   * files written by a concurrent transaction.
   */
  string predicate = 3;
}
Delete Compatibility
Delete modifies an existing fragment, so there may be conflicts with other operations on overlapping fragments. Generally these conflicts are rebaseable or retryable.
These are the operations that conflict with delete:
- Overwrite
- Restore
- UpdateMemWalState
These operations conflict with delete but can be retried:
- Merge (only if there are overlapping fragments)
- Rewrite (only if there are overlapping fragments)
- DataReplacement (only if there are overlapping fragments)
These operations conflict with delete but can potentially be rebased. The deletion masks from the two operations will be merged. However, if both operations modified the same rows, then the conflict becomes a retryable conflict.
- Delete
- Update
Overwrite
Creates or completely overwrites the table with new data, schema, and configuration.
Overwrite protobuf message
message Overwrite {
  /* The new fragments
   *
   * Fragment IDs are not yet assigned.
   */
  repeated DataFragment fragments = 1;
  // The new schema
  repeated lance.file.Field schema = 2;
  // Schema metadata.
  map<string, bytes> schema_metadata = 3;
  // Key-value pairs to merge with existing config.
  map<string, string> config_upsert_values = 4;
  // The base paths to be added for the initial dataset creation
  repeated BasePath initial_bases = 5;
}
Overwrite Compatibility
An overwrite operation completely overwrites the table. Generally, we do not care what has happened since the read version.
However, the overwrite does not necessarily rewrite the table config. As a result, we consider the following to be retryable conflicts:
- UpdateConfig (only if the two operations modify the same config key)
- Overwrite (always)
- UpdateMemWalState (always)
CreateIndex
Adds, replaces, or removes secondary indices (vector indices, scalar indices, full-text search indices).
CreateIndex protobuf message
CreateIndex Compatibility
Indexes record which fragments are covered by the index and we don't require all fragments be covered. As a result, it is typically ok for an index to be created concurrently with the addition of new fragments. These new fragments will simply be unindexed.
Updates and deletes are also compatible with index creation. This is because it is ok for an index to refer to deleted rows. Those results will be filtered out after the index search. If an update occurs then the old value will be filtered out and the new value will be considered part of the unindexed set.
If two CreateIndex operations are committed concurrently then it is allowed. If the indexes have different names this is no problem. If the indexes have the same name then the second operation will win and replace the first.
These operations conflict with index creation:
- Overwrite
- Restore
- UpdateMemWalState
Data replacement operations will conflict with index creation if the column being replaced is being indexed. Rewrite operations will conflict with index creation if the rewritten fragments are covered by the index. This is because an index refers to row addresses and the rewrite operation changes the row addresses. However, if a fragment reuse index is being used, or if the stable row ids feature is enable, then the rewrite operation is compatible with index creation. As a result, these are the operations that are retryable conflicts with index creation:
- Rewrite (only if overlapping fragments, no stable row ids, and no fragment reuse index)
- DataReplacement (only if the column being replaced is being indexed and
data_changeis not false)
Some indices are special singleton indices. For example, the fragment reuse index and the mem wal index. If a conflict occurs between two operations that are modifying the same singleton index, then we must rebase the operation and merge the indexes. As a result, these are the operations that are rebaseable conflicts with index creation:
- CreateIndex (only if both operations are modifying the same singleton index)
Rewrite
Reorganizes data without semantic modification.
This includes operations such as compaction, defragmentation, and re-ordering.
Rewrite operations change row addresses, requiring index updates.
New fragment IDs must be reserved via ReserveFragments before executing a Rewrite transaction.
A rewrite that defers index remapping publishes its address mapping in the same commit by replacing the Fragment Reuse Index entry in the manifest's index section.
Rewrite protobuf message
message Rewrite {
  /* The old fragments that are being replaced
   *
   * DEPRECATED: use groups instead.
   *
   * These should all have existing fragment IDs.
   */
  repeated DataFragment old_fragments = 1;
  /* The new fragments
   *
   * DEPRECATED: use groups instead.
   *
   * These fragments IDs are not yet assigned.
   */
  repeated DataFragment new_fragments = 2;

  /* During a rewrite an index may be rewritten.  We only serialize the UUID
   * since a rewrite should not change the other index parameters.
   */
  message RewrittenIndex {
    // The id of the index that will be replaced
    UUID old_id = 1;
    // the id of the new index
    UUID new_id = 2;
    // the new index details
    google.protobuf.Any new_index_details = 3;
    // the version of the new index
    uint32 new_index_version = 4;
    /* Files in the new index with their sizes.
     * Empty if file sizes are not available (e.g. older writers).
     */
    repeated IndexFile new_index_files = 5;
  }

  // A group of rewrite files that are all part of the same rewrite.
  message RewriteGroup {
    /* The old fragment that is being replaced
     *
     * This should have an existing fragment ID.
     */
    repeated DataFragment old_fragments = 1;
    /* The new fragment
     *
     * The ID should have been reserved by an earlier
     * reserve operation
     */
    repeated DataFragment new_fragments = 2;
  }

  // Groups of files that have been rewritten
  repeated RewriteGroup groups = 3;
  // Indices that have been rewritten
  repeated RewrittenIndex rewritten_indices = 4;
}
Rewrite Compatibility
Rewrite operations do not change data but they can materialize deletions and they do replace fragments. As a result, they can potentially conflict with other operations that modify the fragments being rewritten.
These are the operations that conflict with rewrite:
- Overwrite
- Restore
Rewrite is not compatible with CreateIndex by default because the operation will change the row addresses that the CreateIndex refers to. However, a fragment reuse index or the stable row ids feature can allow these operations to be compatible.
Several operations modify existing fragments. As a result, they can potentially conflict with Rewrite if they modify the same fragments. However, Merge is overly general and so no conflict detection is possible. As a result, here are the operations that are retryable conflicts with Rewrite:
- Merge (always)
- DataReplacement (only if overlapping fragments)
- Delete (only if overlapping fragments)
- Update (only if overlapping fragments)
- Rewrite (if overlapping fragments or both carry a fragment reuse index)
- CreateIndex (overlapping fragments and no fragment reuse index or stable row ids)
There is one case where a Rewrite will rebase. This is when the Rewrite operation has a fragment reuse index and there is a CreateIndex operation that is writing the fragment reuse index. In this case the Rewrite will rebase and update its fragment reuse index to include the conflicting fragment reuse index.
As a result, these are the operations that are rebaseable conflicts with Rewrite:
- CreateIndex (if the CreateIndex is writing the fragment reuse index and the Rewrite is carrying a fragment reuse index)
Merge
Adds new columns to the table, modifying the schema. All fragments must be updated to include the new columns.
Merge protobuf message
message Merge {
  /* The updated fragments
   *
   * These should all have existing fragment IDs.
   */
  repeated DataFragment fragments = 1;
  // The new schema
  repeated lance.file.Field schema = 2;
  // Schema metadata.
  map<string, bytes> schema_metadata = 3;
  /* Set when this merge makes no nullability-affecting schema change: it
   * introduces no field that data staged against an earlier schema could
   * not safely omit. Without the assertion (including transactions written
   * before this field existed) the merge conservatively conflicts with
   * concurrent value-writes, which can only cause a retry.
   */
  bool preserves_nullability = 4;
}
Overly General Operation
The Merge operation is a very generic operation. The set of fragments provided in the operation will be the final set of fragments in the resulting dataset. As a result, it has a high potential for conflicts with other operations. If possible, more restrictive operations such as Rewrite, DataReplacement, or Append should be preferred over Merge.
Merge Compatibility
As mentioned above, Merge is a very generic operation, as a result it has a high potential for conflicts with other operations. The following operations conflict with Merge:
- Overwrite
- Restore
- UpdateMemWalState
- Project
These operations are retryable conflicts with Merge:
- Update (always)
- Append (always)
- Delete (always)
- Merge (always)
- Rewrite (always)
- DataReplacement (always)
Project
Removes columns from the table, modifying the schema. This is a metadata-only operation; data files are not modified.
Project protobuf message
message Project {
  // The new schema
  repeated lance.file.Field schema = 1;
  /* Set when this projection makes no nullability-affecting schema change,
   * as a rename or a drop does not. Without the assertion (including
   * transactions written before this field existed) the projection
   * conservatively conflicts with concurrent value-writes, which can only
   * cause a retry. A nullability tightening must not set this.
   */
  bool preserves_nullability = 2;
}
Project Compatibility
Since project only modifies the schema, it is compatible with most other operations. However, it is not compatible with Merge because the Merge operation modifies the schema (can potentially add columns) and the logic to rebase those changes does not currently exist (project is cheap and easy enough to retry).
These are the operations that conflict with Project:
- Overwrite
- Restore
- UpdateMemWalState
The following operations are retryable conflicts with Project:
- Project (always)
- Merge (always)
Restore
Reverts the table to a previous version.
Restore Compatibility
The Restore operation reverts the table to a previous version. It's generally assumed this trumps any other operation. Here are the operations that conflict with Restore:
- UpdateMemWalState
- UpdateConfig (only if it updates schema or field metadata, which a restore rewinds)
ReserveFragments
Pre-allocates fragment IDs for use in future Rewrite operations.
This allows rewrite operations to reference fragment IDs before the rewrite transaction is committed.
ReserveFragments Compatibility
The ReserveFragments operation is fairly trivial. The only thing it changes is the max fragment id. So this only conflicts with operations that modify the max fragment id. Here are the operations that conflict with ReserveFragments:
- Overwrite
- Restore
Clone
Creates a shallow or deep copy of the table.
Shallow clones are metadata-only copies that reference original data files through base_paths.
Deep clones are full copies using object storage native copy operations (e.g., S3 CopyObject).
Clone protobuf message
message Clone {
  /* - true:  Performs a metadata-only clone (copies manifest without data files).
   *          The cloned dataset references original data through `base_paths`,
   *          suitable for experimental scenarios or rapid metadata migration.
   * - false: Performs a full deep clone using the underlying object storage's native
   *          copy API (e.g., S3 CopyObject, GCS rewrite). This leverages server-side
   *          bulk copy operations to bypass download/upload bottlenecks, achieving
   *          near-linear speedup for large datasets (typically 3-10x faster than
   *          manual file transfers). The operation maintains atomicity and data
   *          integrity guarantees provided by the storage backend.
   */
  bool is_shallow = 1;
  /* the reference name in the source dataset
   * in most cases it should be the branch or tag name in the source dataset
   */
  optional string ref_name = 2;
  // the version of the source dataset for cloning
  uint64 ref_version = 3;
  // the absolute base path of the source dataset for cloning
  string ref_path = 4;
  // if the target dataset is a branch, this is the branch name of the target dataset
  optional string branch_name = 5;
}
Clone Compatibility
The Clone operation can only be the first operation in a dataset. If there is an existing dataset, then the Clone operation will fail. As a result, there is no such thing as a conflict with Clone.
Update
Modifies row values without adding or removing rows. Supports two execution modes: REWRITE_ROWS deletes rows in current fragments and rewrites them in new fragments, which is optimal when the majority of columns are modified or only a small number of rows are affected; REWRITE_COLUMNS fully rewrites affected columns within fragments by tombstoning old column versions, which is optimal when most rows are affected but only a subset of columns are modified.
Update protobuf message
message Update {
  /* The fragments that have been removed. These are fragments where all rows
   * have been updated and moved to a new fragment.
   */
  repeated uint64 removed_fragment_ids = 1;
  // The fragments that have been updated.
  repeated DataFragment updated_fragments = 2;
  // The new fragments where updated rows have been moved to.
  repeated DataFragment new_fragments = 3;
  // The ids of the fields that have been modified.
  repeated uint32 fields_modified = 4;
  /// SSTables to mark as compacted after this transaction.
  repeated CompactedSsTable compacted_sstables = 5;
  /* The fields that used to judge whether to preserve the new frag's id into
   * the frag bitmap of the specified indices.
   */
  repeated uint32 fields_for_preserving_frag_bitmap = 6;
  // The mode of update
  UpdateMode update_mode = 7;
  /* Filter for checking existence of keys in newly inserted rows, used for conflict detection.
   * Only tracks keys from INSERT operations during merge insert, not updates.
   */
  optional lance.transaction.KeyExistenceFilter inserted_rows = 8;
  /* Per-fragment physical row offsets that matched an update_columns hash join (RewriteColumns).
   * Deprecated: use updated_fragment_offset_bitmaps (field 10) instead.
   */
  map<uint64, UInt32List> updated_fragment_offsets = 9;
  /* Per-fragment matched offsets as portable RoaringBitmap bytes (replaces field 9).
   * Writers emit field 10 only. Readers prefer field 10; fall back to field 9 for
   * manifests written before this change.
   */
  map<uint64, bytes> updated_fragment_offset_bitmaps = 10;
  /* The `dir_id` of the MemWAL `compacted_sstables` belongs to; required
   * when `compacted_sstables` is non-empty. See UpdateMemWalState.dir_id.
   */
  optional string mem_wal_dir_id = 11;
}
Update Compatibility
Here are the operations that conflict with Update:
- Overwrite
- Restore
An update operation is both a delete and an append operation. Like a Delete operation, it will modify fragments to change the deletion mask. As a result, there will be a retryable conflict with other operations that modify the same fragments. Here are the operations that are retryable conflicts with Update:
- Rewrite (only if overlapping fragments)
- DataReplacement (only if overlapping fragments)
- Merge (always)
Similar to Delete, the Update operation can rebase other modifications to the deletion mask. Here are the operations that are rebaseable conflicts with Update:
- Delete
- Update
UpdateConfig
Modifies table configuration, table metadata, schema metadata, or field metadata without changing data.
UpdateConfig protobuf message
message UpdateConfig {
  lance.transaction.UpdateMap config_updates = 6;
  lance.transaction.UpdateMap table_metadata_updates = 7;
  lance.transaction.UpdateMap schema_metadata_updates = 8;
  map<int32, lance.transaction.UpdateMap> field_metadata_updates = 9;

  // Deprecated -------------------------------
  map<string, string> upsert_values = 1;
  repeated string delete_keys = 2;
  map<string, string> schema_metadata = 3;
  map<uint32, FieldMetadataUpdate> field_metadata = 4;

  message FieldMetadataUpdate {
    map<string, string> metadata = 5;
  }
}
UpdateConfig Compatibility
An UpdateConfig operation only modifies table config and tends to be compatible with other operations. Here are the operations that conflict with UpdateConfig:
- Overwrite
- Restore (only if the UpdateConfig updates schema or field metadata)
- UpdateConfig (only if the two operations modify the same config)
DataReplacement
Replaces the data files backing some fields of existing fragments with new data files, without moving rows. Each
DataReplacementGroup names a target fragment and one new data file for it. A fragment can be the target of several
groups, one per new file, and different groups can carry different fields.
The groups apply in order, each to the target fragment as it stands when the transaction commits (and as the previous groups left it), not to the fragment as the writer read it:
- If one of the fragment's data files lists the same field ids as the new file, in the same order and file version, the new file's path, size and base replace that data file's.
- If none of the fragment's data files holds any of the new file's fields (for example, a column added as all nulls), the new file is appended.
- If the fragment's data files hold all of the new file's fields, those fields are replaced with the tombstone id (
-2) in the files that hold them, and the new file is appended. A data file left with no field of the schema and none of the fragment's spilled row lineage is removed from the fragment. A legacy (V1) data file can't tombstone single fields, so a field a V1 file holds can only be replaced by an exact match. - Any other replacement is rejected.
data_change says whether the new files change any value. When it is absent, as in every transaction written before
the field existed, it means true. A replacement that changes data:
- withdraws, from every index on a replaced field, its coverage of the target fragments;
- tombstones the replaced fields in the target fragments' overlays committed at or before its read version, since the new base values supersede them (see DataOverlay);
- with stable row IDs, sets the last-updated-at version of every row in the target fragments to the new version.
With data_change false, the writer asserts that the new files hold, for every physical row, the same base values the
fragment's files held for those fields (overlays not applied), only laid out in different files. No value a reader sees
changes, so none of the above happens: index coverage is kept, overlays keep shadowing the base, and no row's
last-updated-at version moves. Nor does it count as writing values against a concurrent Project or Merge that may change
a field's nullability. A compaction that repacks a fragment's columns into fewer files is such a replacement.
DataReplacement protobuf message
message DataReplacement {
  /* A fragment can be the target of several groups, one per new file. The
   * groups apply in order, each to the fragment as the previous ones left it.
   */
  repeated DataReplacementGroup replacements = 1;
  /* Whether the new files change any value. Absent means true, which is what
   * a writer that predates this field meant. False means the values were only
   * moved to new files: index coverage, overlays, and row update versions are
   * left as they are.
   */
  optional bool data_change = 2;
}
DataReplacement Compatibility
A DataReplacement operation only replaces the data of the fields its new files carry. As a result, it can be safer and simpler than Merge or Update operations. It rewrites column files positionally against the fragments it targets, so a concurrent operation conflicts when it removes one of those fragments or one of the replaced fields, moves or rewrites the rows the column files cover, or depends on the replaced values. Here are the operations that conflict with DataReplacement (non-retryable):
- Overwrite
- Restore
- UpdateMemWalState
- Delete (only if it removes a target fragment outright)
- Update (only if it removes a target fragment outright)
- Project (only if it drops a field being replaced)
The last three are retryable instead when data_change is false: a replacement that only moves values can be planned
again against the new version, while one that changes data would need new values from its caller.
The following operations are retryable conflicts with DataReplacement:
- DataReplacement (only if same field and overlapping fragments)
- CreateIndex (only if the field being replaced is being indexed, and
data_changeis not false) - Rewrite (only if overlapping fragments)
- Update (only if it rewrites rows out of a target fragment, or rewrites one of the replaced fields in place)
- Merge (always)
A concurrent Delete or Update that only adds a deletion vector to a target fragment (without removing it) is compatible: the positional column file stays aligned and the rebase preserves the deletion vector.
DataOverlay
Attaches overlay files to fragments, supplying new values
for a subset of (row offset, field) cells without rewriting the fragments' base
data files. The overlays are appended to each fragment's existing overlays list,
so overlays written by concurrent commits are preserved. Each overlay's
committed_version is stamped to the new dataset version at commit time (and
re-stamped on retry), like the created-at / last-updated-at version sequences.
DataOverlay protobuf message
message DataOverlay {
  repeated DataOverlayGroup groups = 1;
}

message DataOverlayGroup {
  uint64 fragment_id = 1;
  /* Each DataOverlayFile.committed_version is left 0 by the writer and stamped
   * to the new dataset version at commit time (re-stamped on retry), in the
   * same way as the created-at / last-updated-at version sequences. The fields
   * touched are read from each overlay's `data_file.fields`.
   */
  repeated DataOverlayFile overlays = 2;
}
DataOverlay Compatibility
A DataOverlay operation only changes cells within existing fragments and preserves
physical row addresses, so — like DataReplacement — it is intentionally permissive.
Because overlays stack and the higher committed_version wins each covered cell,
independent backfills never conflict, and a concurrent Delete simply makes the
overlay value for a deleted offset inert. Here are the operations that conflict
with DataOverlay:
- Overwrite
- Restore
- UpdateMemWalState
The following operations are retryable conflicts with DataOverlay:
- Rewrite (only if overlapping fragments) — row-rewriting compaction or an overlay→base fold changes physical row addresses or consumes the overlays, so the overlay's offsets are no longer valid; the writer must re-read the new fragment, recompute, and retry.
- Merge (always).
- A row-moving Update that touches an overlaid fragment — a delete-and-reinsert
update (any update that is not a
REWRITE_COLUMNScolumn rewrite) relocates the updated rows into new fragments, so the overlay's physical offsets no longer address them; the writer must re-read and retry.
DataOverlay is compatible with another DataOverlay (any fields), Append, Delete, a
REWRITE_COLUMNS column rewrite, and DataReplacement, because all of these
preserve physical row addresses: overlay offsets stay valid, the overlay is newer
and wins its covered cells, and the version gate excludes those cells from any
rebuilt index.
When a DataReplacement or a REWRITE_COLUMNS update writes new base values for a
field, it supersedes any older overlay on that field: the writer tombstones the
overlay's entry for the rewritten field — replacing the field id with the obsolete
sentinel, as with obsolete base columns — so the fresh base values are not silently
shadowed. Overlay entries for other fields are preserved, and an overlay left with
no live fields is dropped. A DataReplacement with data_change false writes no new
values, so it tombstones nothing.
UpdateMemWalState
Updates the state of MemWal indices (write-ahead log based indices).
UpdateMemWalState protobuf message
UpdateBases
Adds new base paths to the table, enabling reference to data files in additional locations.
UpdateBases protobuf message
UpdateBases Compatibility
An UpdateBases operation only modifies the base paths. As a result, it only conflicts with other UpdateBases operations and even then only conflicts if the two operations have base paths with the same id, name, or path.
Action-Based Transactions (Transaction V2)
Readers before v14.0.0 fail on a CompositeOperation
Any reader can open and scan a table version committed as a
CompositeOperation: the inline transaction lives in manifest field 23,
which older readers ignore
(#9482, v14.0.0). A
reader before v14.0.0 that decodes the transaction itself, to read the
transaction history or to check a concurrent commit for conflicts, fails
on the unrecognized operation. For conflict checking that failure aborts
the older writer's commit, which is the safe outcome.
Writers commit a CompositeOperation only when the calling code opts in
per commit.
Every operation above is a single named verb. A transaction may instead carry a
CompositeOperation: an ordered list of granular actions that apply
atomically as one manifest change. This lets one commit express a change no
single named operation covers, such as appending a fragment and updating table
config together, and makes the transaction a true diff of the manifest rather
than a description of intent.
CompositeOperation protobuf message
A CompositeOperation holds UserSteps, each a human-recognizable step with
a description, which in turn hold the granular Actions applied to the
manifest. The two levels support multi-statement transactions: each statement
becomes one step, so the transaction history still shows what each statement
did, while all of the steps' actions apply as one atomic change.
Actions are deltas rather than post-images, and an action that allocates a new identifier (a field, fragment, or base id) names it with a local placeholder. When building the manifest before commit, the local placeholders are translated into concrete identifiers. Both properties, true deltas and local placeholders, are what let a composite operation be replayed against a newer version, or onto a different branch, without rewriting it.
A committed identifier, by contrast, must have been allocated by the operation's read version: it is at or below the read version's high-water mark for that id space, either naming an existing object or, for a fragment, an id an earlier commit reserved. Apply rejects a committed fragment, field, or base id above the mark, since a concurrent commit may have minted it for an unrelated object in the meantime.
The full action vocabulary and the reasoning behind its shape are defined in
protos/transaction/actions.proto.
Actions apply in order, with one exception: ReserveFragmentIds and
ReserveRowIds are summed and taken after the operation's own mints, wherever
they appear. A reservation creates nothing another action can reference, so
this has no other visible effect within the operation, and a fragment can claim
a reserved id only from an earlier commit's reservation. ResetTable discards
objects but never rewinds the id counters.
data_unchanged is per action and defaults to false. true asserts the action
changes no row's values: the rows it adds, removes, or rebinds are the same
logical rows with the same values before and after, as when compaction moves
rows or a column file is re-encoded. Change-data-capture readers emit rows only
from actions where it is false, and one operation may mix both. A writer that
omits it claims a data change, which is the conservative reading.
On a TombstoneFieldData, the flag is the inverse of
DataReplacement.data_change. A tombstone that changes data tombstones the fields' entries in the
fragment's overlays, since new base values supersede them, and withdraws every
index on those fields from the fragment. A tombstone with data_unchanged true
is one half of a re-encode: the same operation re-binds every tombstoned field
in that fragment with an AddDataFile that also has data_unchanged true and
holds the same base values (overlays not applied) for every physical row. No
value a reader sees changes, so overlays keep shadowing the base, index
coverage is kept, and no row's last-updated-at version moves. Nor does it count
as writing values against a concurrent overlay of those fields, a concurrent
index build over them, or a concurrent change that makes one of them required.
It does count as a write against AssertCellsUnchanged and AssertUniqueKeys:
apply cannot verify that the values are unchanged, and those assertions guard
correctness. Apply rejects an unchanged tombstone whose fields are not all
re-bound that way, and an AddDataFile whose data_unchanged differs from
that of the tombstone it re-binds.
Fragment Reuse History
The fragment reuse history is not an index in
a CompositeOperation. Apply rejects AddIndexSegment, RemoveIndexSegment,
AdjustIndexCoverage, and DropIndex when they name __lance_frag_reuse.
The history changes only through two actions, and neither refers to the
history's index entry, its UUID, or its index_version. A ResetTable
discards the history along with the indices.
AppendFragReuseTransition records that a compaction in the same operation
moved rows from its sources to its destinations, with one ordered
compaction or stable partition mapping. It is a delta: on every commit attempt,
apply appends the transition to the history as it stands on the version being
committed on top of, never to a copy the writer read. Transitions with disjoint
sources therefore commute. The transition carries no fragment digests. Apply
derives each source digest from the fragment as it stands (its physical rows
and deleted rows) and each destination digest from its AddFragment (its
physical rows and no deleted rows).
Apply validates the transition without reading any file, and rejects it unless:
- every source is removed in the same operation by a
RemoveFragmentwithdata_unchangedtrue; - every destination is added in the same operation by an
AddFragment, under a local or a reserved committed id, and has no deletion file; - each source's surviving-row count in the mapping equals its physical rows minus its deleted rows, and the sources' surviving rows total the destinations' physical rows;
- no source is consumed by any other transition, in the history or in the same operation;
- every index on the table returns row addresses. The history translates row
addresses, so it would mistranslate an index that returns stable row ids,
which only a table with stable row ids can have. For the same reason, an
AddIndexSegmentfor an index that returns stable row ids must not be committed while the history is tagged (index_version1 or higher); - a stable partition has between 1 and 65,536 destinations.
Apply then creates the history if the table has none, converts a version 0
history to version 1 (keeping its legacy_versions), sets
FLAG_FRAGMENT_REUSE_INDEX, and, on a table with stable row ids, also sets
FLAG_FRAG_REUSE_WITH_STABLE_ROW_IDS. A history over the inline size limit is
written to an external details file.
Recording a transition is never required. A compaction that moves covered rows without one is legal: the indices lose coverage of those rows, which are then scanned, and since fragment ids are never reused nothing is served wrongly. Recording a transition on every compaction is a writer default, not a rule apply enforces. The writer is responsible only for the mapping payload being correct.
TrimFragReuse is declarative. On every commit attempt, apply drops every
transition that no index on the version being committed on top of still needs.
It names no transition, so it never conflicts; an implementation may keep a
transition it cannot prove unneeded.
Neither action adds a conflict claim of its own. A transition's sources are
removed by RemoveFragments in the same operation, which already make two
compactions of the same fragment, or a compaction and a concurrent deletion
from one of its sources, conflict.
Index Builds and Removed Fragments
An AddIndexSegment requires the data it covers, and so does an
AdjustIndexCoverage for the fragments it adds: a concurrent commit that
replaces those fields' values in place (an AddDataFile or a
TombstoneFieldData with data_unchanged false, or an AlterField of one of the
fields) conflicts with it, because a reader cannot tell from the metadata that
the indexed values changed. Removing a whole fragment does not conflict with
that requirement. Like a deletion or an overlay, a removal is visible in the
metadata: a segment naming a removed fragment either reaches its rows through
the fragment reuse history or loses that coverage. So neither a removal nor a
compaction conflicts with building an index, whether or not the compaction
records a transition, and this does not depend on what else the removing
operation contains. A data file written into a committed fragment still
conflicts with that fragment's removal, which destroys the written cells, and
an AdjustIndexCoverage still requires each committed fragment it adds to
exist.
After such a race, an index can hold two segments whose coverage overlaps once the history is applied: one built late over a compacted source, and one built over the destination. A reader must serve a fragment from a segment that covers it directly rather than translating another segment's coverage through the history, so the overlap never returns a row twice. Apply does not prune the overlap; dropping the superseded segment is the index maintenance's concern, and it only ever loses coverage; it is never a conflict.
Isolation
Two CompositeOperations conflict when they change the same part of the
manifest in ways that cannot both apply, or when one breaks a precondition the
other asserts. Some changes to the same part do both apply: two overlays of the
same cells both land and the newer wins, an overlay and a re-encode of its
column both land, and fragment reuse transitions with disjoint sources both
append to the history. Without
assertions this is snapshot isolation: concurrent writers that each read a
value the other overwrites can both commit. A writer whose values depend on
what it read must declare the read with AssertCellsUnchanged. For example,
UPDATE t SET a = b and UPDATE t SET b = a from the same snapshot write
disjoint columns, so without assertions both commit and the columns end up
swapped, which neither serial order produces (either leaves them equal); each
declaring the column it read makes the second commit conflict.
Compatibility
A CompositeOperation produces an ordinary manifest, so a reader that scans a
table whose latest version was written this way needs no knowledge of the
feature. Readers are affected in two places:
- A reader that decodes the transaction itself — reading the transaction history, or checking a concurrent commit for conflicts — sees an operation it does not recognize. Implementations must reject it rather than treat it as a no-op, so that a concurrent V2 commit aborts an in-flight commit instead of being silently skipped.
- Transactions are usually inlined into the manifest. Opening a table never
requires decoding them (see
Inline Transaction Sections), so an
undecodable inline
CompositeOperationdoes not prevent reading data.
Conflict resolution between two CompositeOperations is computed from the
actions themselves. Between a CompositeOperation and any named operation it
fails closed: the commit is rejected as a conflict rather than compared.
Conflict Resolution
Terminology
When concurrent transactions attempt to commit against the same read version, Lance employs conflict resolution to determine whether the transactions can coexist. Three outcomes are possible:
-
Rebasable: The transaction can be modified to incorporate concurrent changes while preserving its semantic intent. The transaction is transformed to account for the concurrent modification, then the commit is retried automatically within the commit layer.
-
Retryable: The transaction cannot be rebased, but the operation can be re-executed at the application level with updated data. The implementation returns a retryable conflict error, signaling that the application should re-read the data and retry the operation. The retried operation is expected to produce semantically equivalent results.
-
Incompatible: The transactions conflict in a fundamental way where retrying would violate the operation's assumptions or produce semantically different results than expected. The commit fails with a non-retryable error. Callers should proceed with extreme caution if they decide to retry, as the transaction may produce different output than originally intended.
Rebase Mechanism
The TransactionRebase structure tracks the state necessary to rebase a transaction against concurrent commits:
- Fragment tracking: Maintains a map of fragments as they existed at the transaction's read version, marking which require rewriting
- Modification detection: Tracks the set of fragment IDs that have been modified or deleted
- Affected rows: For Delete and Update operations, stores the specific rows affected by the operation for fine-grained conflict detection
- Fragment reuse indices: Accumulates fragment reuse index metadata from concurrent Rewrite operations
When a concurrent transaction is detected, the rebase process:
- Compares fragment modifications to determine if there is overlap
- For Delete/Update operations, compares
affected_rowsto detect whether the same rows were modified - Merges deletion vectors when both transactions delete rows from the same fragment
- Accumulates fragment reuse index updates when concurrent Rewrites change fragment IDs
- Modifies the transaction if rebasable, or returns a retryable/incompatible conflict error
Conflict Scenarios
Rebasable Conflict Example
The following diagram illustrates a rebasable conflict where two Delete operations modify different rows in the same fragment:
gitGraph
    commit id: "v1"
    commit id: "v2"
    branch writer-a
    branch writer-b
    checkout writer-a
    commit id: "Delete rows 100-199" tag: "read_version=2"
    checkout writer-b
    commit id: "Delete rows 500-599" tag: "read_version=2"
    checkout main
    merge writer-a tag: "v3"
    checkout writer-b
    commit id: "Rebase: merge deletion vectors" type: HIGHLIGHT
    checkout main
    merge writer-b tag: "v4"
In this scenario:
- Writer A deletes rows 100-199 and successfully commits version 3
- Writer B attempts to commit but detects version 3 exists
- Writer B's transaction is rebasable because it only modified deletion vectors (not data files) and
affected_rowsdo not overlap - Writer B rebases by merging Writer A's deletion vector with its own, write it to storage
- Writer B successfully commits version 4
Retryable Conflict Example
The following diagram illustrates a retryable conflict where an Update operation encounters a concurrent Rewrite (compaction) that prevents automatic rebasing:
gitGraph
    commit id: "v1"
    commit id: "v2"
    branch writer-a
    branch writer-b
    checkout writer-a
    commit id: "Compact fragments 1-5" tag: "read_version=2"
    checkout writer-b
    commit id: "Update rows in fragment 3" tag: "read_version=2"
    checkout main
    merge writer-a tag: "v3: fragments compacted"
    checkout writer-b
    commit id: "Detect conflict: cannot rebase" type: REVERSE
In this scenario:
- Writer A compacts fragments 1-5 into a single fragment and successfully commits version 3
- Writer B attempts to update rows in fragment 3 but detects version 3 exists
- Writer B's Update transaction is retryable but not rebasable: fragment 3 no longer exists after compaction
- The commit layer returns a retryable conflict error
- The application must re-execute the Update operation against version 3, locating the rows in the new compacted fragment
Incompatible Conflict Example
The following diagram illustrates an incompatible conflict where a Delete operation encounters a concurrent Restore that fundamentally invalidates the operation:
gitGraph
    commit id: "v1"
    commit id: "v2"
    commit id: "v3"
    branch writer-a
    branch writer-b
    checkout writer-a
    commit id: "Restore to v1" tag: "read_version=3"
    checkout writer-b
    commit id: "Delete rows added in v2-v3" tag: "read_version=3"
    checkout main
    merge writer-a tag: "v4: restored to v1"
    checkout writer-b
    commit id: "Detect conflict: incompatible" type: REVERSE
In this scenario:
- Writer A restores the table to version 1 and successfully commits version 4
- Writer B attempts to delete rows that were added between versions 2 and 3
- Writer B's Delete transaction is incompatible: the table has been restored to version 1, and the rows it intended to delete no longer exist
- The commit fails with a non-retryable error
- If the caller retries the deletion operation against version 4, it would either delete nothing (if those rows don't exist in v1) or delete different rows (if similar row IDs exist in v1), producing semantically different results than originally intended
External Manifest Store
If the backing object store does not support atomic operations (rename-if-not-exists or put-if-not-exists), an external manifest store can be used to enable concurrent writers.
An external manifest store is a key-value store that supports put-if-not-exists operations. It is the concurrency coordinator and fast version index: its conditional write selects one immutable staging manifest for each version. The canonical manifest bytes in object storage remain authoritative, so the external store supplements but does not replace them. A reader unaware of the external manifest store can still read the table, but may observe a version up to one commit behind the true latest version.
Commit Process with External Store
The commit process follows a four-step protocol:

- Stage manifest:
PUT_OBJECT_STORE {dataset}/_versions/{version}.manifest-{uuid} - Write the new manifest to object storage under a unique path determined by a new UUID
-
This staged manifest is not yet visible to readers
-
Reserve version in external store:
PUT_EXTERNAL_STORE base_uri, version, {dataset}/_versions/{version}.manifest-{uuid} - Atomically reserve the version for this staged manifest using put-if-not-exists
- The reservation selects one immutable staging object; it is not yet the canonical commit
-
If this operation fails due to conflict, another writer reserved this version
-
Finalize in object store:
COPY_OBJECT_STORE {dataset}/_versions/{version}.manifest-{uuid} → {dataset}/_versions/{version}.manifest - Copy the staged manifest to the final path
- Successful materialization at this deterministic path is the commit point
-
This makes the manifest discoverable by readers unaware of the external store
-
Update external store pointer:
PUT_EXTERNAL_STORE base_uri, version, {dataset}/_versions/{version}.manifest - Update the external store to point to the finalized manifest path
- After copying, read the canonical object's current metadata. Return its ETag to the caller as an opaque physical-generation observation so runtime caches do not collapse a newly committed Dataset into an older cached Dataset at the same URI and version
- Do not persist that ETag in the external store. Concurrent finalizers can copy the same selected immutable bytes into different physical generations, and COPY plus external-store publication is not atomic. Every helper therefore publishes the same stable path-and-size tuple
- Completes the synchronization between external store and object storage
Fault Tolerance:
If the writer fails after step 2 but before step 3, the external store contains a pending reservation. Readers that use the external store detect this state and retry materialization. If step 3 succeeds but step 4 fails, the canonical object remains committed; readers use it and may repair the external index. Staging deletion is garbage collection and does not affect the commit outcome.
Rolling Upgrade:
Roll this behavior out normally across the fleet. New readers ignore legacy stored ETags, and legacy readers already accept finalized rows without an ETag, so mixed-version rows remain compatible. While both legacy finalizers and legacy readers remain, the pre-existing race can still republish a stale ETag that a legacy reader rejects. Full protection takes effect when the rolling upgrade converges; no row migration or quiesced cutover is required.
Reader Process with External Store
The reader follows a validation and synchronization protocol:
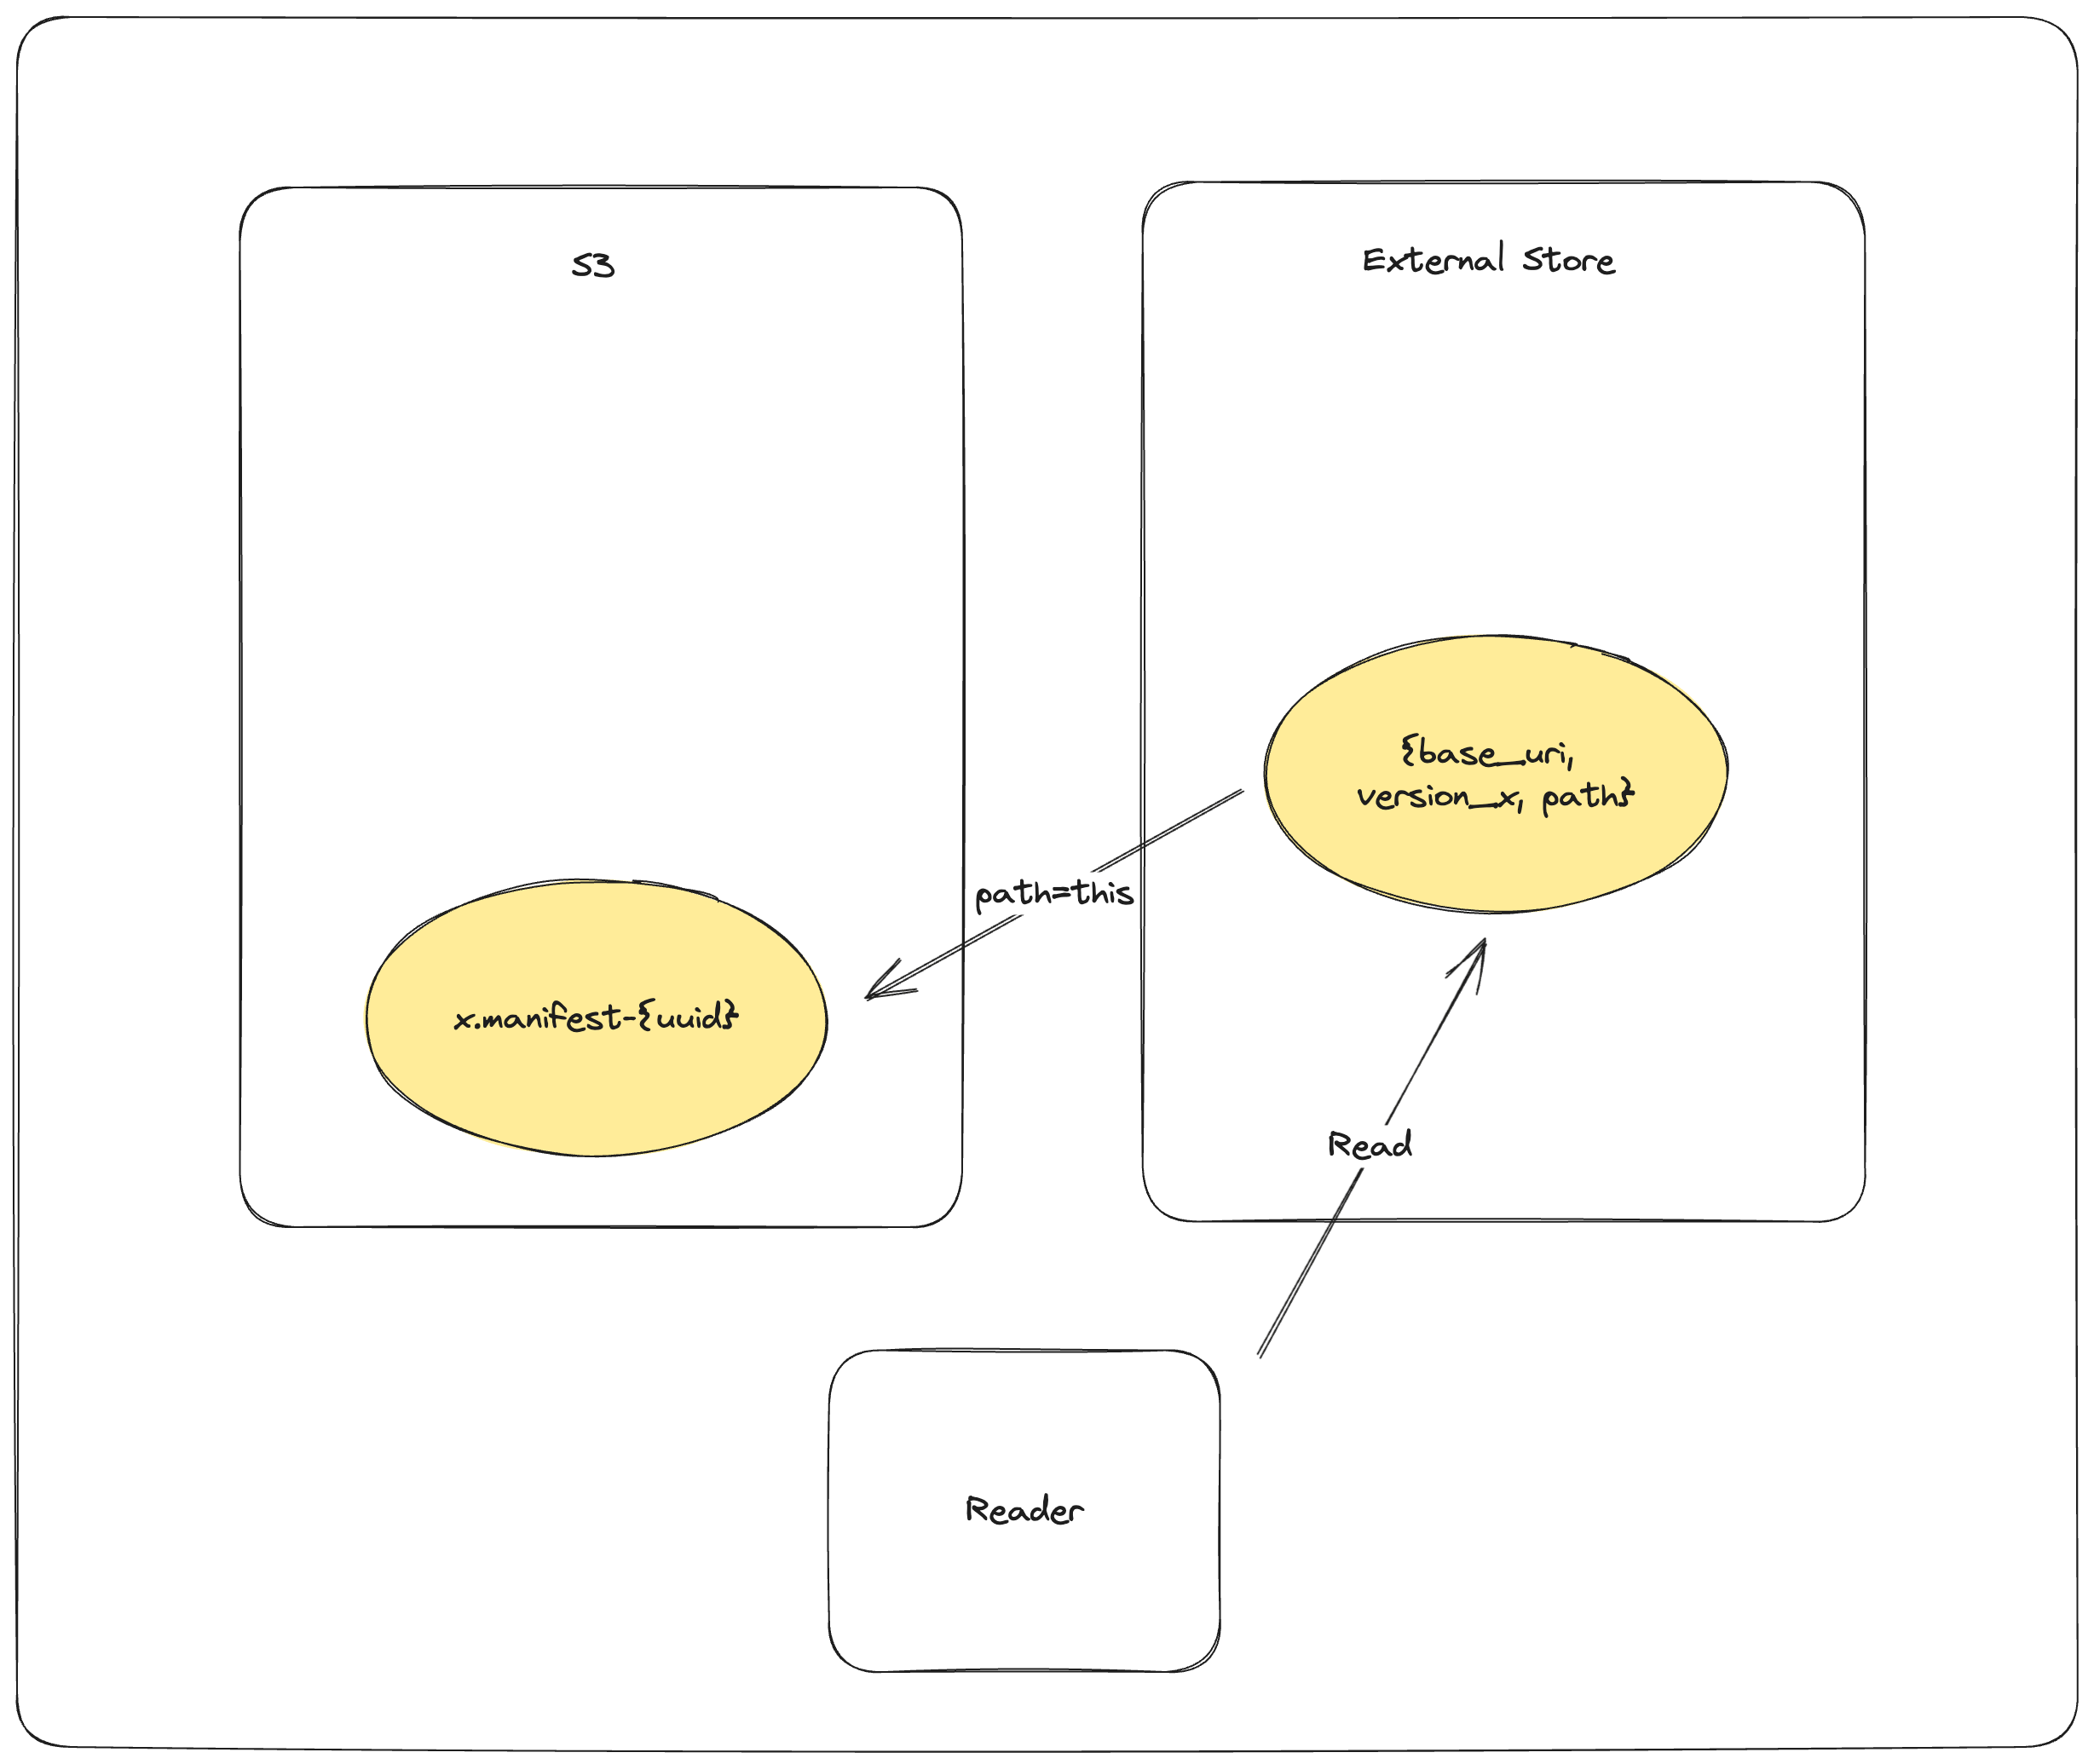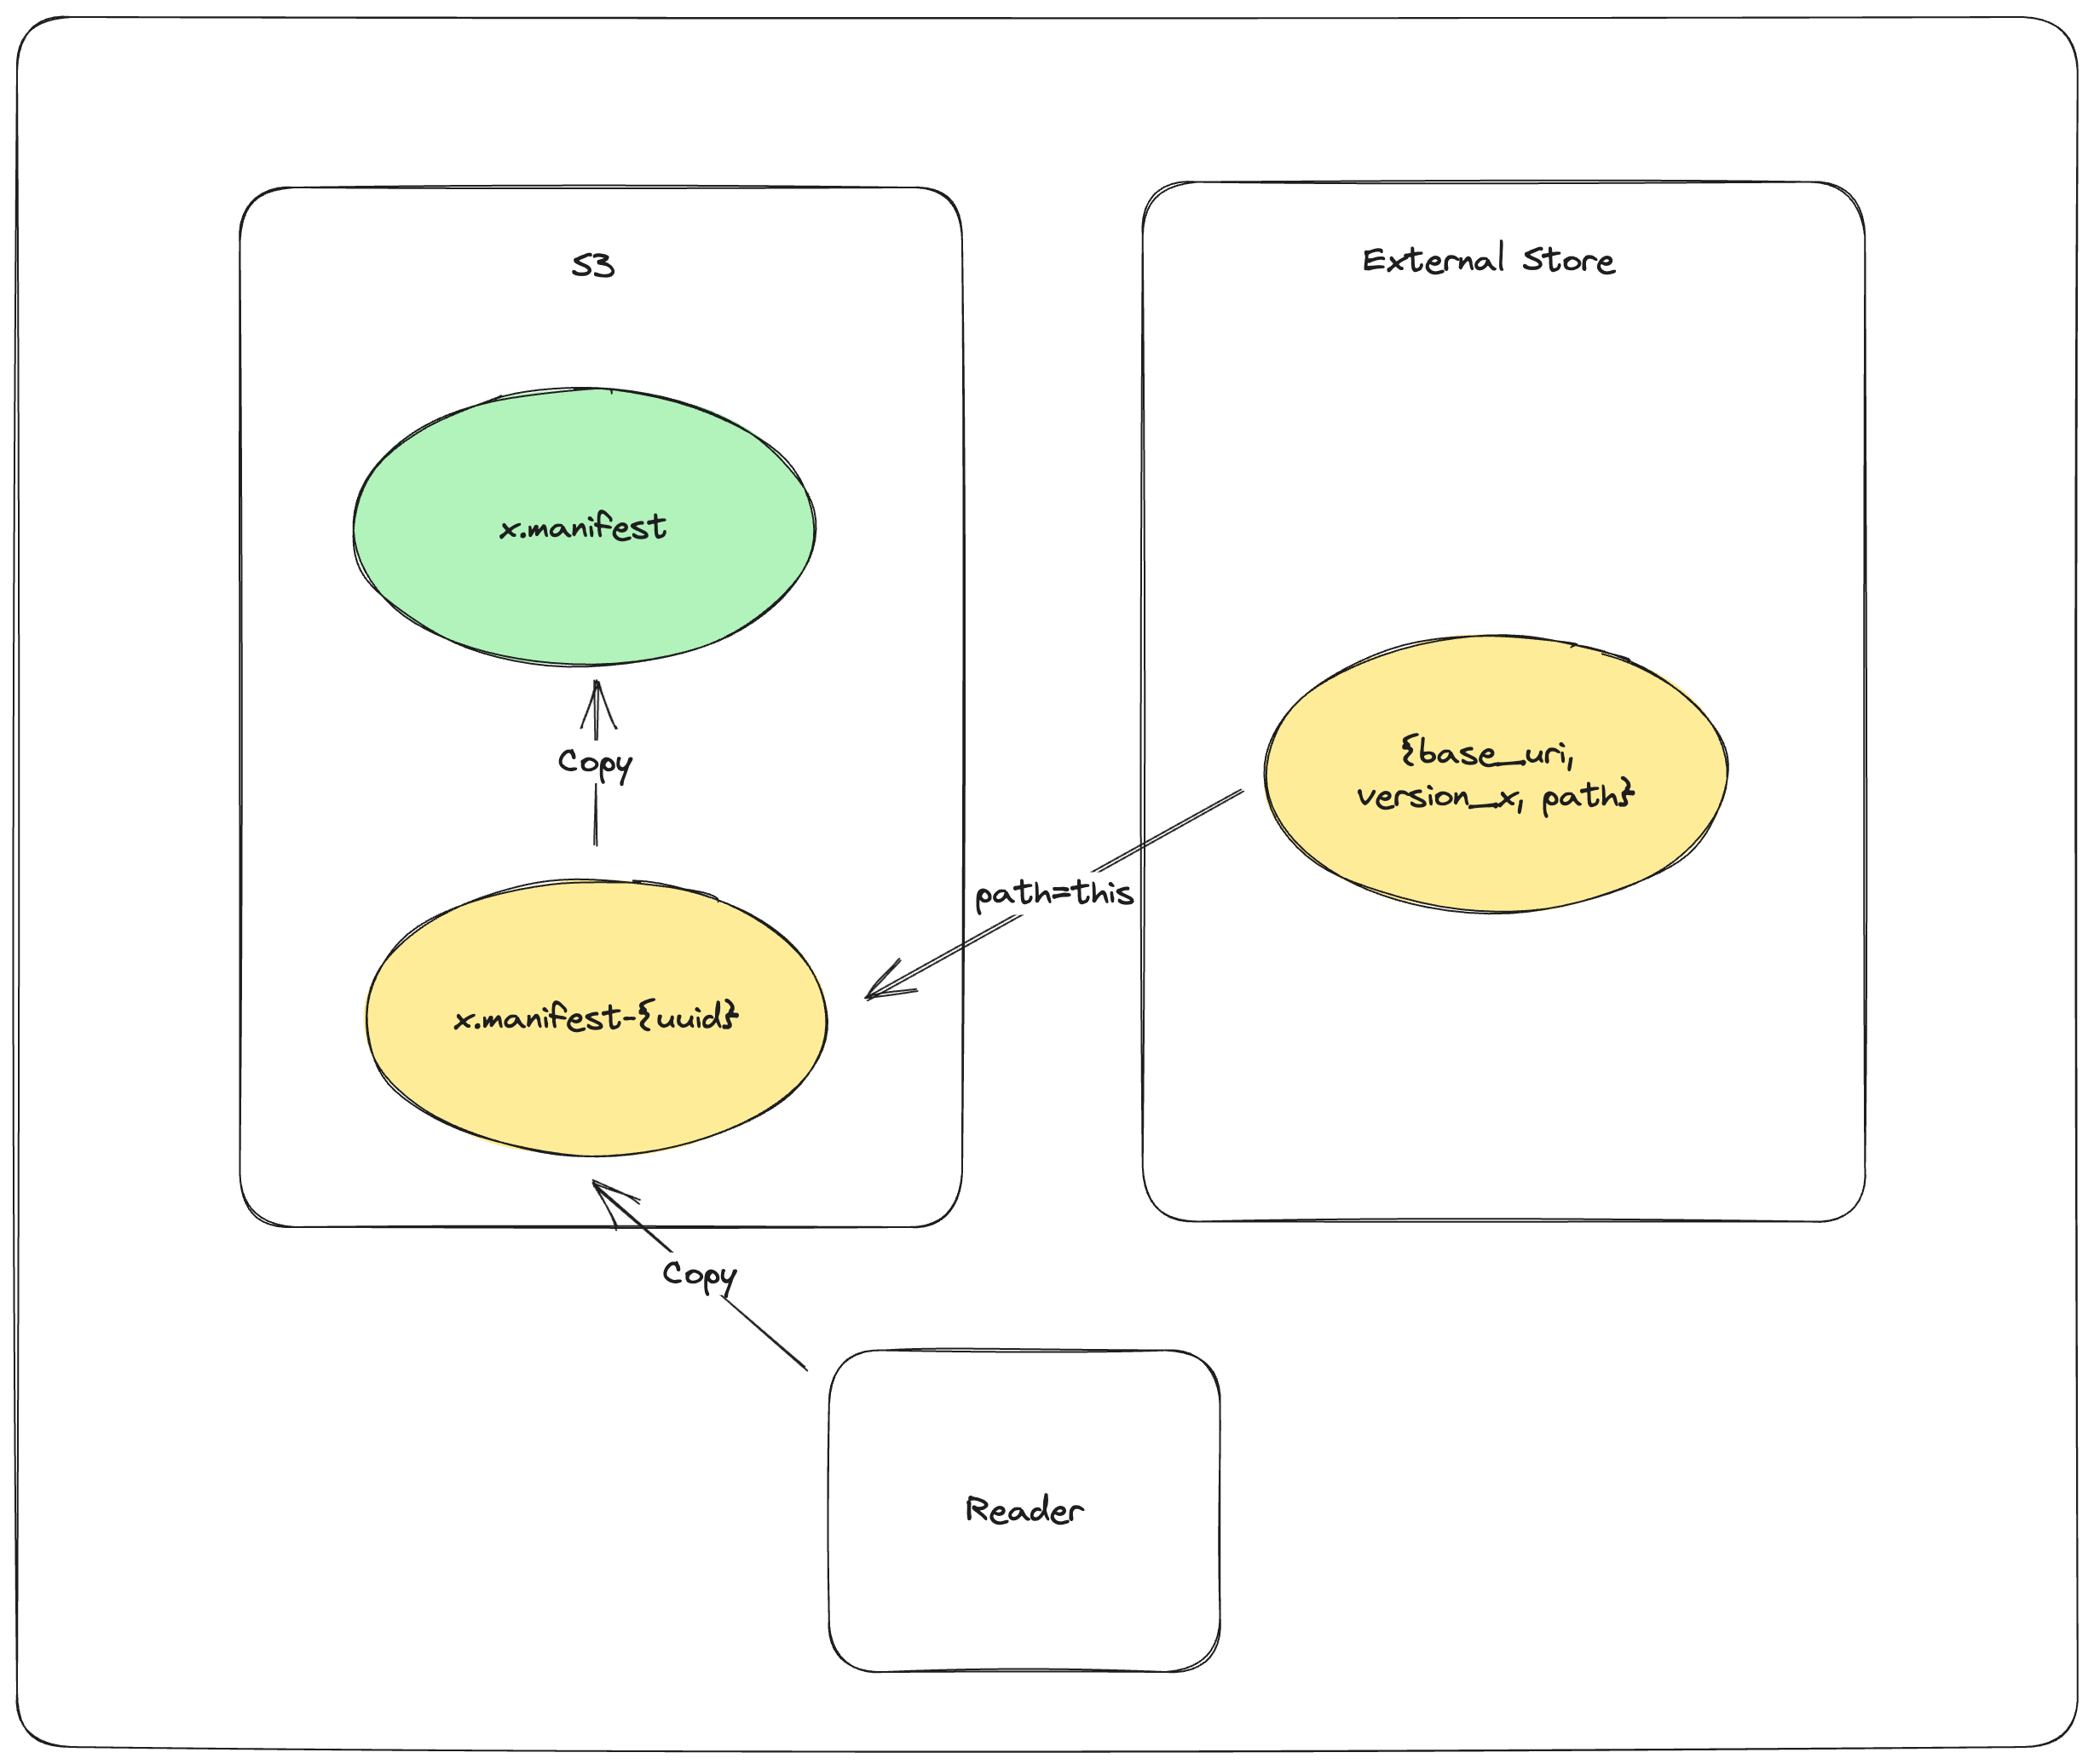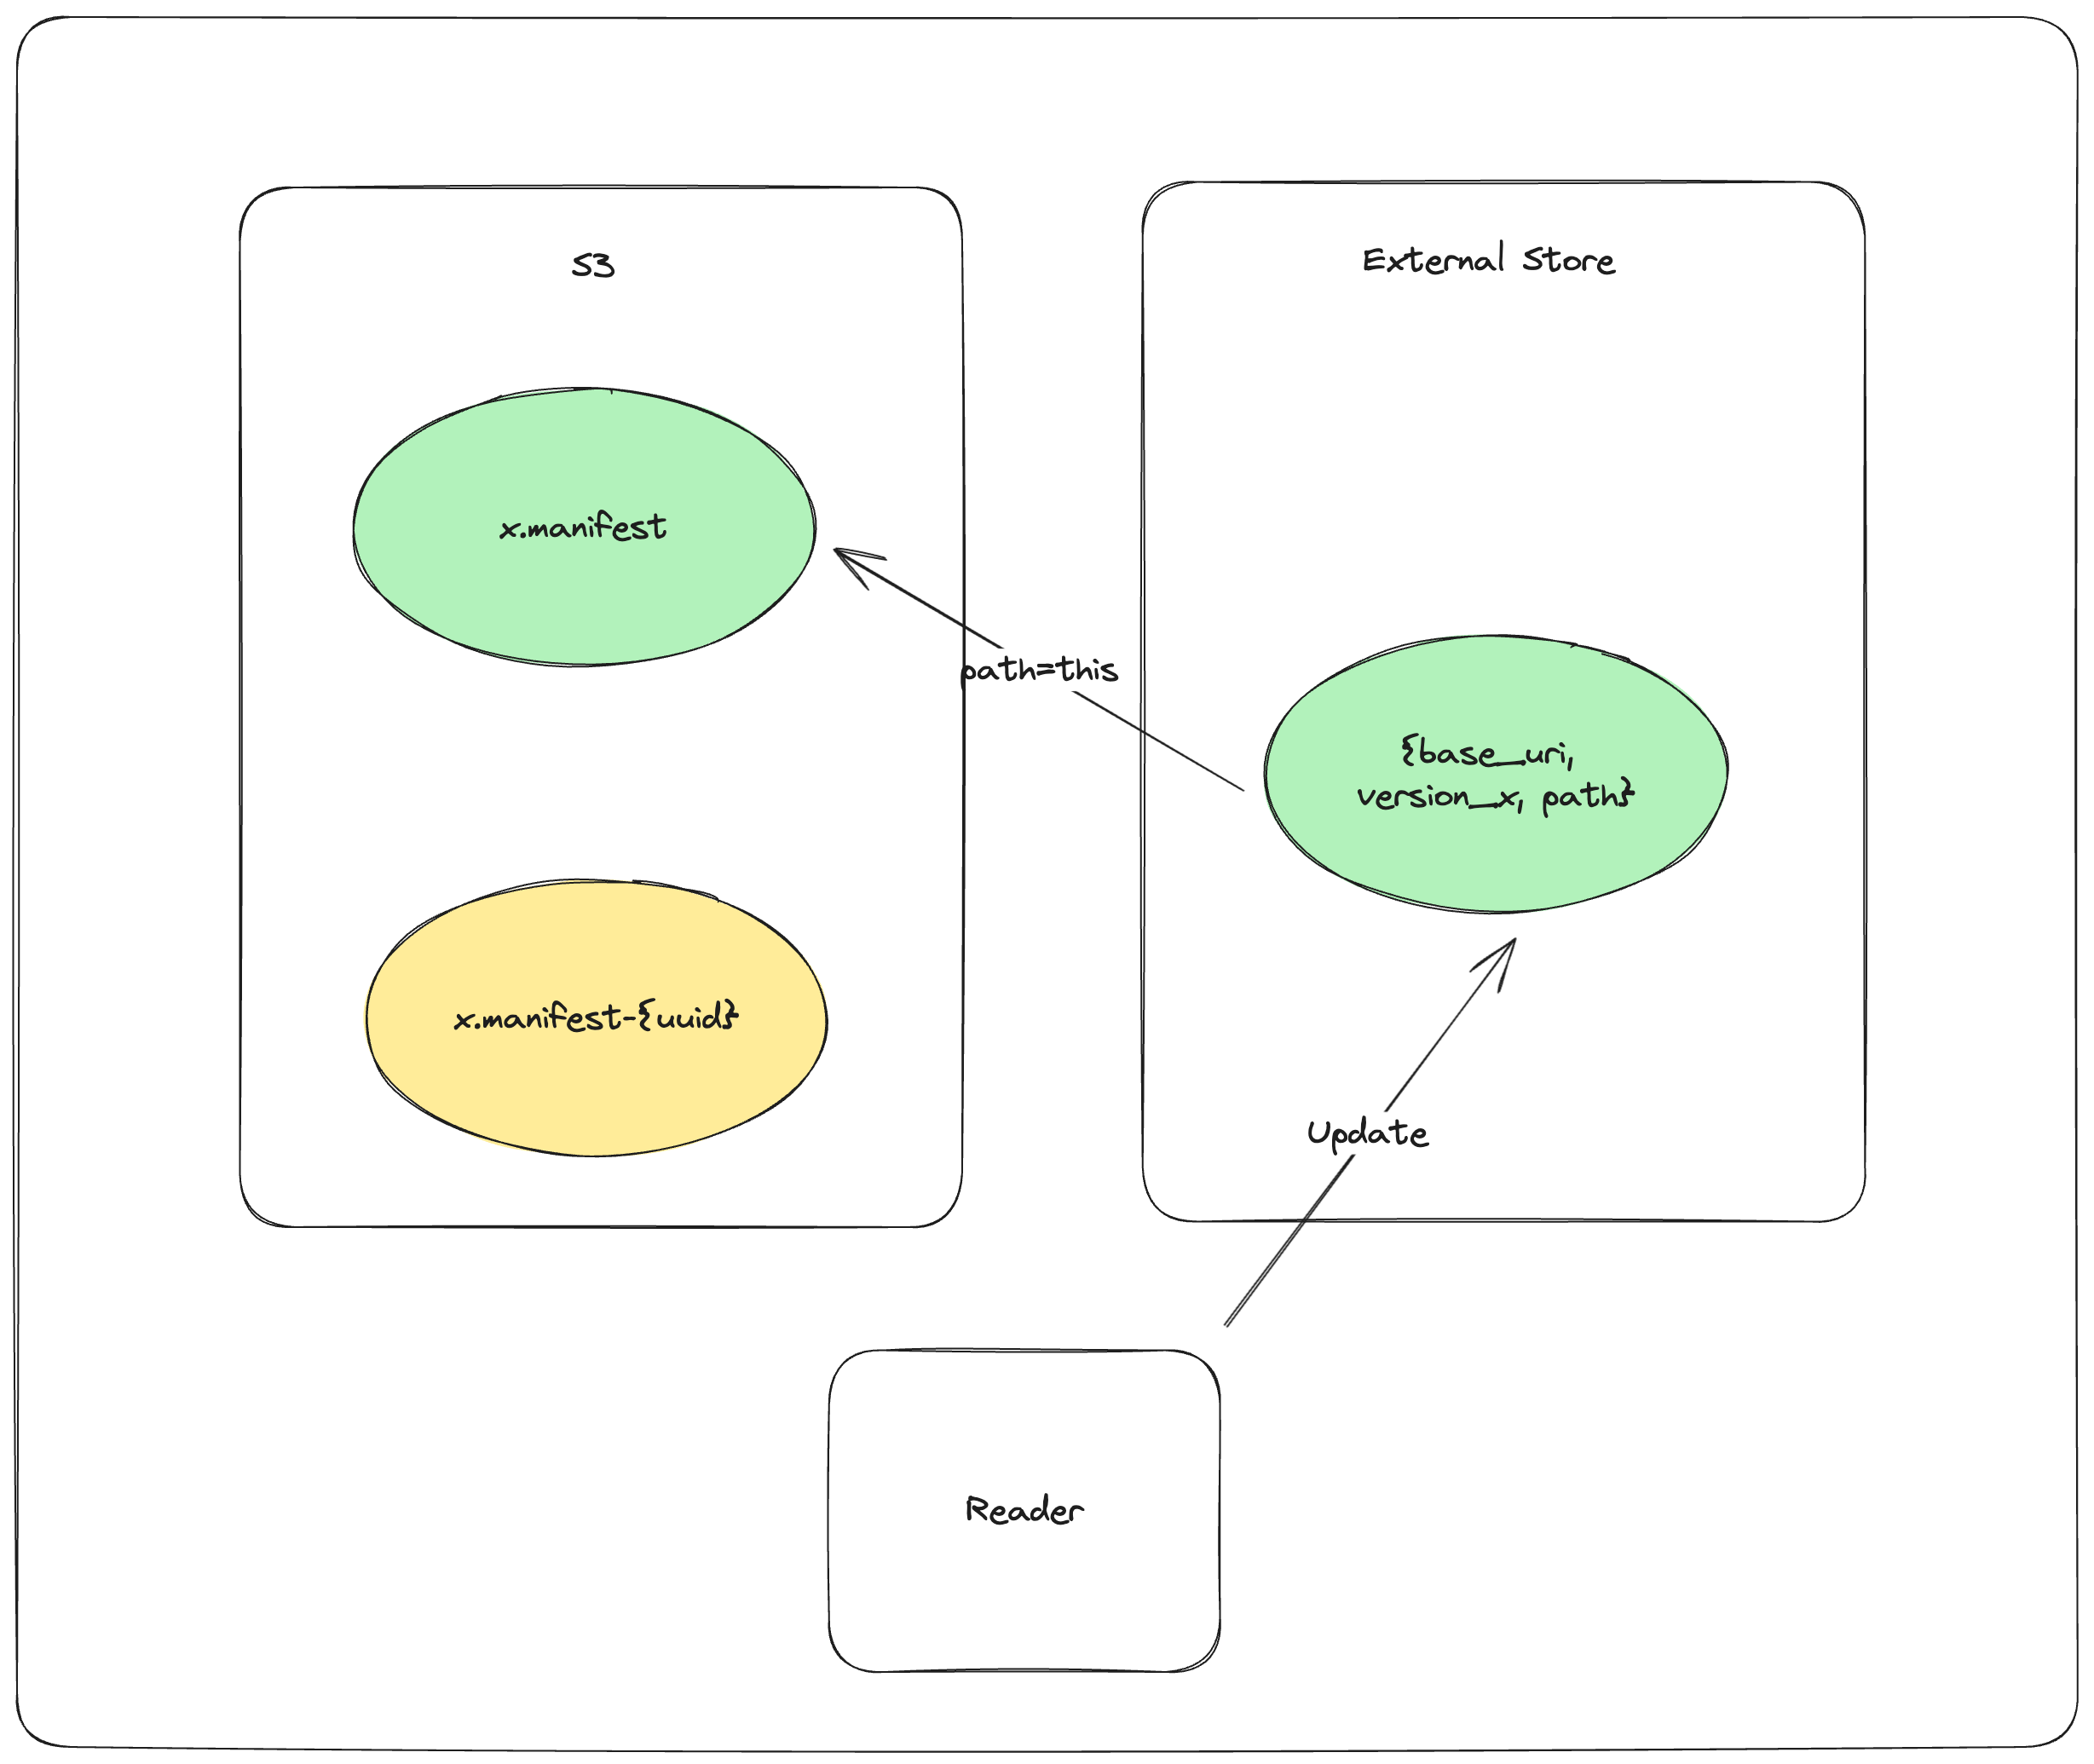
- Query external store:
GET_EXTERNAL_STORE base_uri, version→path - Retrieve the manifest path for the requested version
- If the path does not end with a UUID, validate the canonical object's size. Ignore any legacy stored ETag because it is neither content identity nor dataset-incarnation identity; the validation HEAD still returns the current canonical ETag to the caller
-
If the path ends with a UUID, synchronization is required
-
Synchronize to object store:
COPY_OBJECT_STORE {dataset}/_versions/{version}.manifest-{uuid} → {dataset}/_versions/{version}.manifest - Attempt to finalize the staged manifest
-
This operation is idempotent
-
Update external store:
PUT_EXTERNAL_STORE base_uri, version, {dataset}/_versions/{version}.manifest - Best-effort record the finalized path and size without an ETag while returning the observed destination ETag to the current caller
-
If this index repair fails, retain staging so a future reader can retry it
-
Return finalized path: Return
{dataset}/_versions/{version}.manifest - Return once canonical materialization succeeds, even if index repair or staging cleanup fails
- If canonical materialization cannot be established, or an observed size differs, return an error
This protocol ensures that datasets using external manifest stores remain portable: copying the dataset directory preserves all data without requiring the external store.